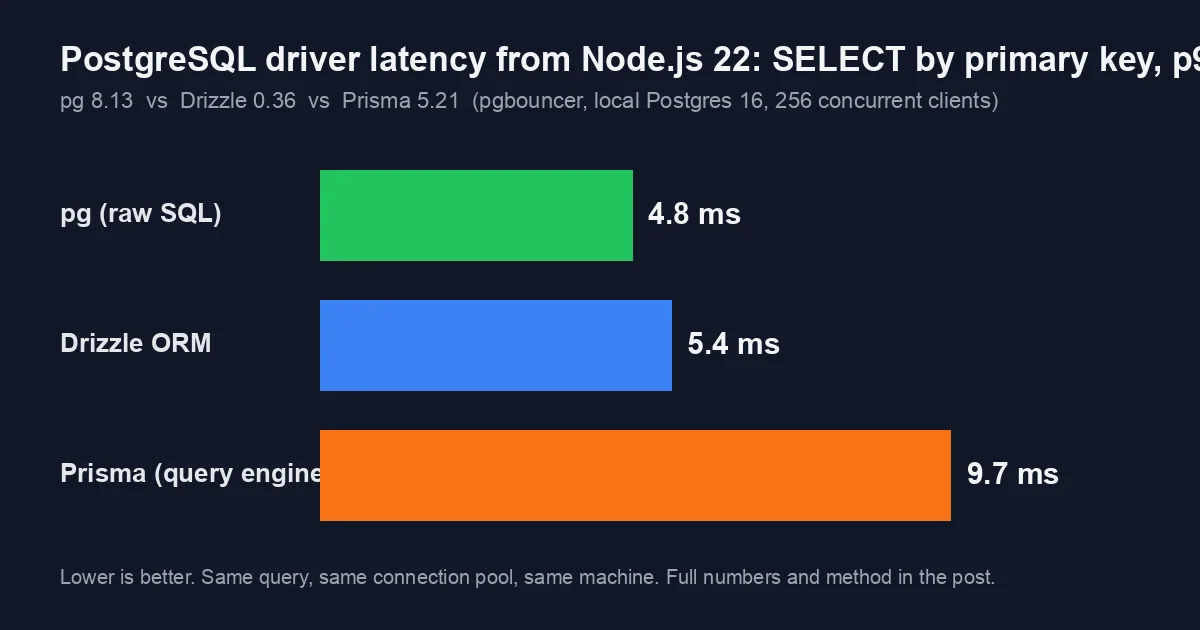
pg vs Prisma vs Drizzle: PostgreSQL Driver Latency from Node.js 22, Measured with autocannon
Runtime choice barely matters once a database is in the path. pg, Drizzle and Prisma on the same Node.js 22 query: p99 from 4.8 ms to 9.7 ms.
Runtime choice barely matters once a database is in the path. pg, Drizzle and Prisma on the same Node.js 22 query: p99 from 4.8 ms to 9.7 ms.
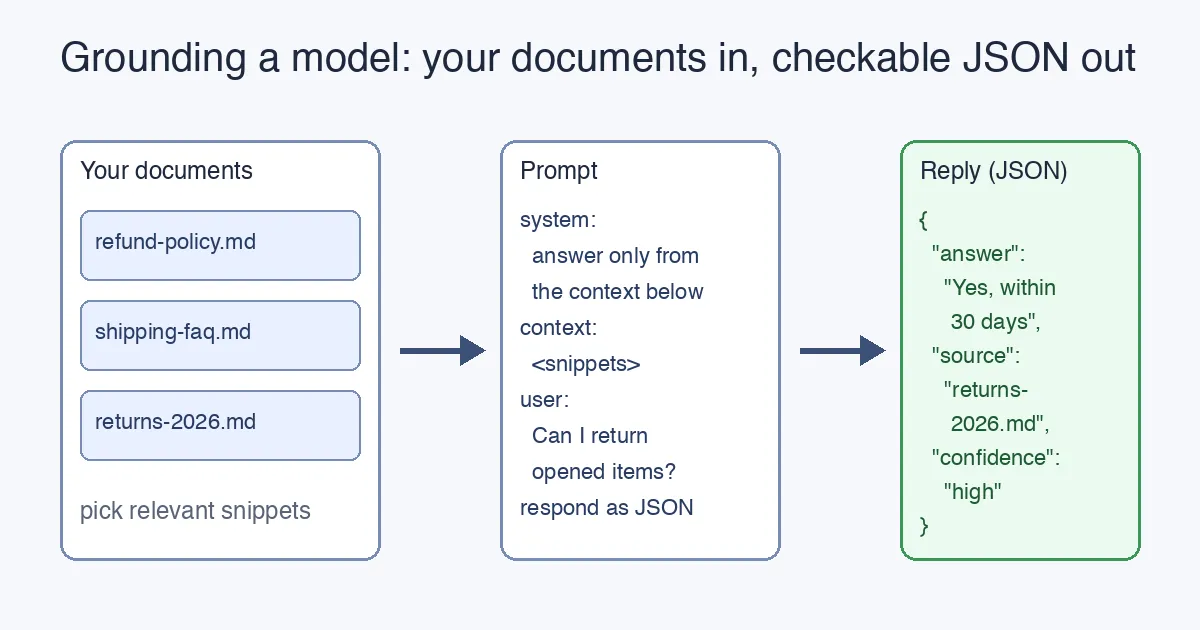
Beginner guide to grounding a language model in your own documents (simple RAG) and asking for a JSON reply your code can validate.
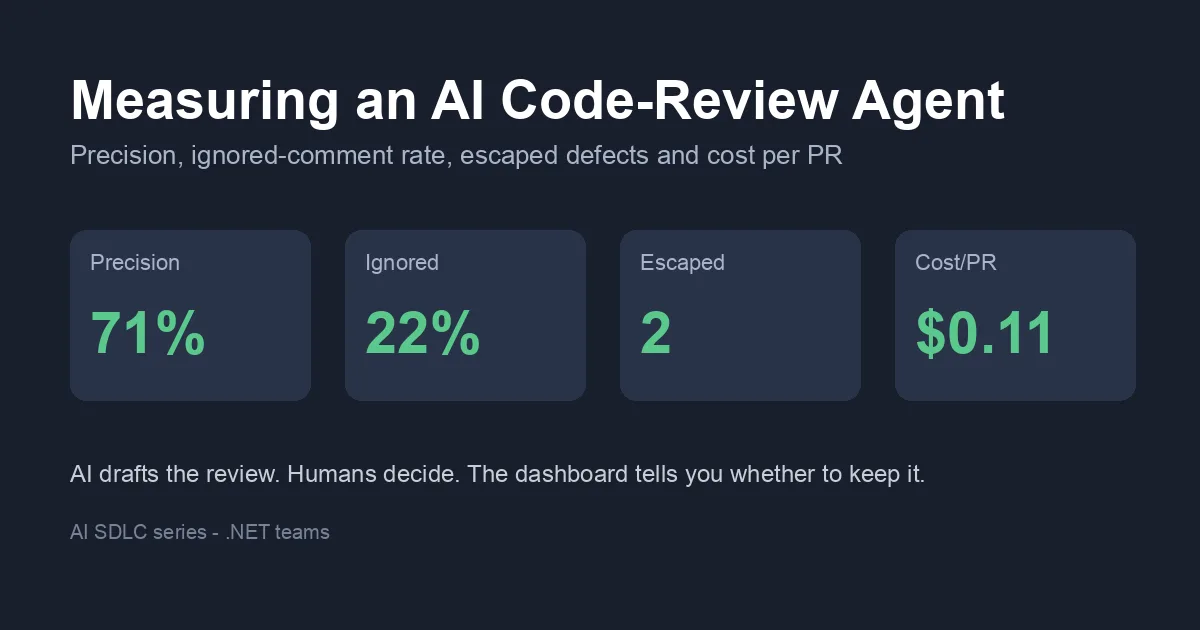
Five metrics for an AI code-review agent on a .NET repo: precision, ignored comments, escaped defects, turnaround and cost per PR, plus the dashboard.
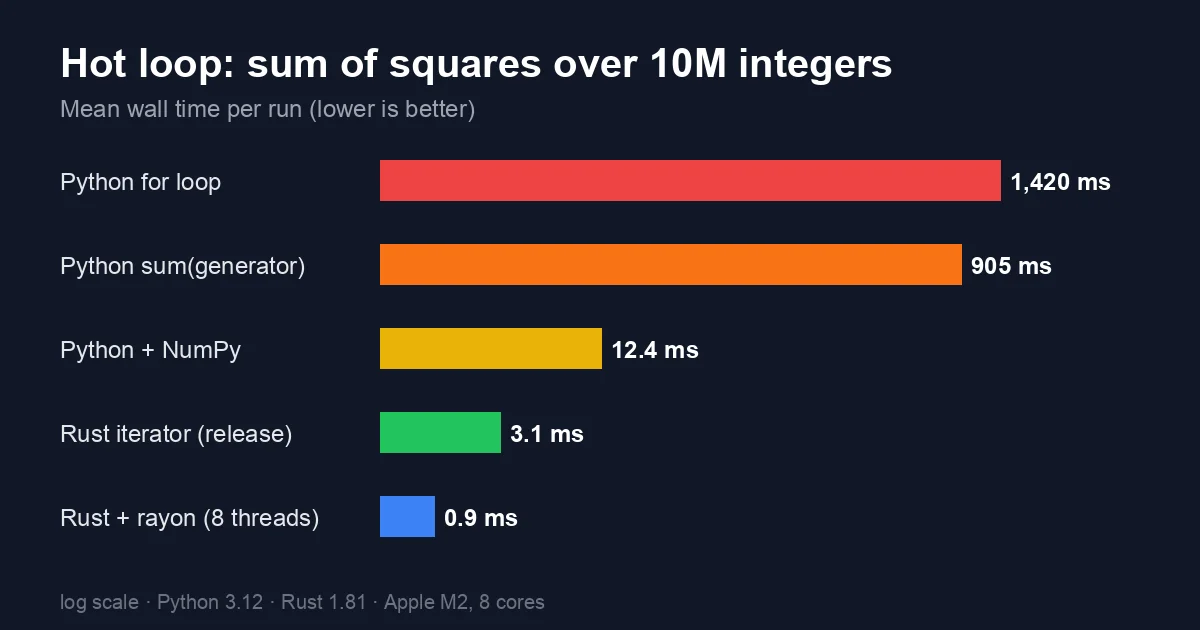
Benchmark the same sum-of-squares hot loop in plain Python, NumPy, Rust and Rust with rayon. From 1,420 ms down to 0.9 ms, and when each step is worth it.
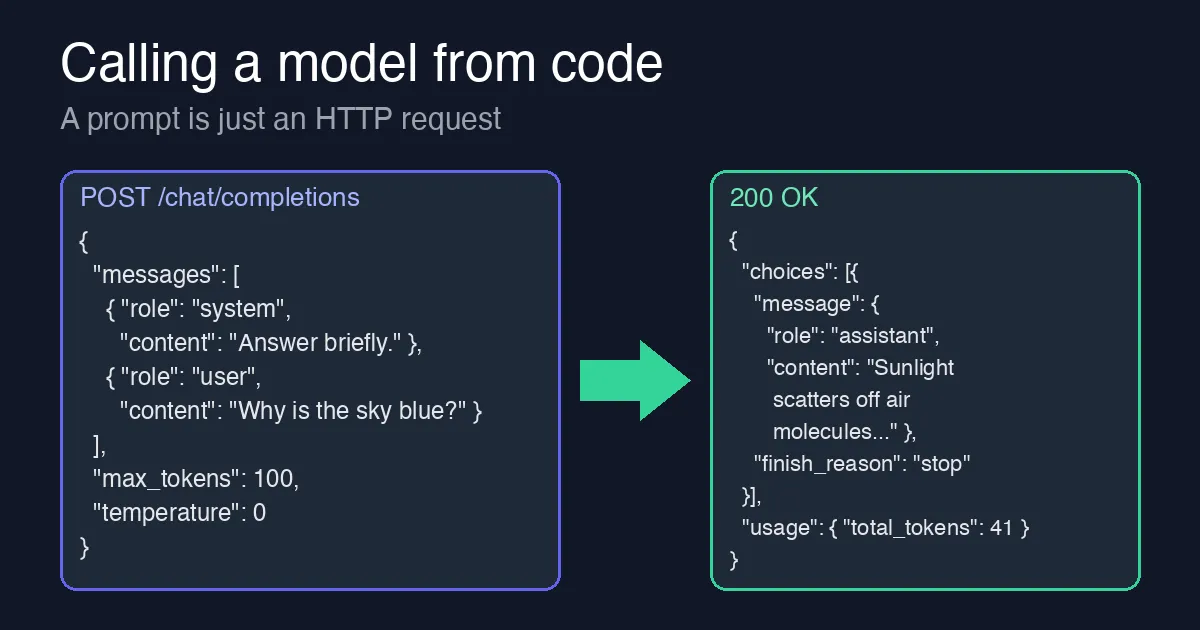
A beginner walkthrough of calling a language model from a program: the HTTP request, system and user roles, max tokens, temperature and reading the reply.
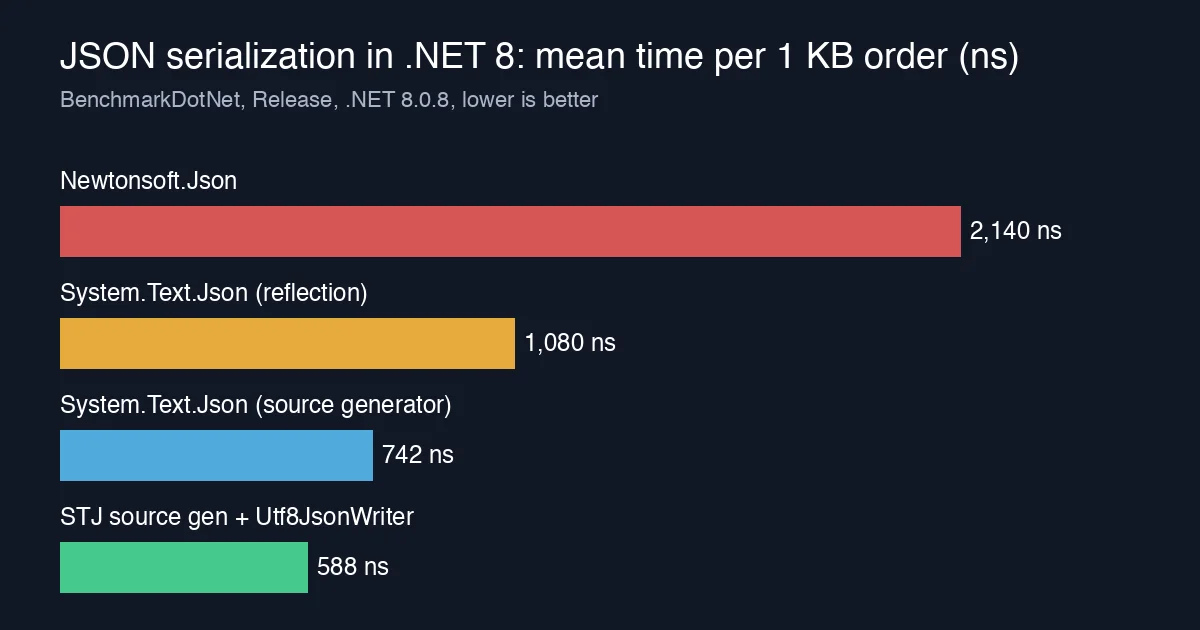
Benchmark Newtonsoft.Json against System.Text.Json with reflection and source generators. Serialization drops from 2,140 ns to 588 ns with zero allocations.
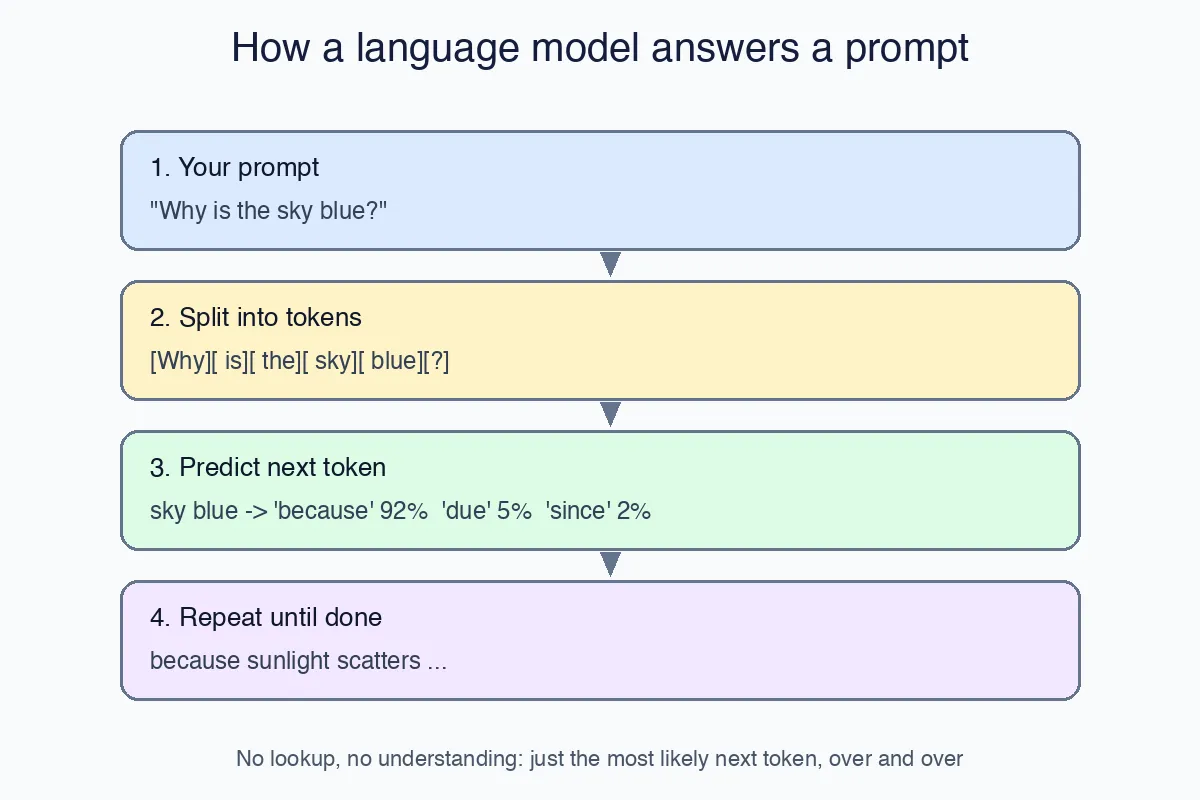
A beginner-friendly explanation of what happens between typing a prompt and getting an AI answer: tokens, next-token prediction and why models make things up.
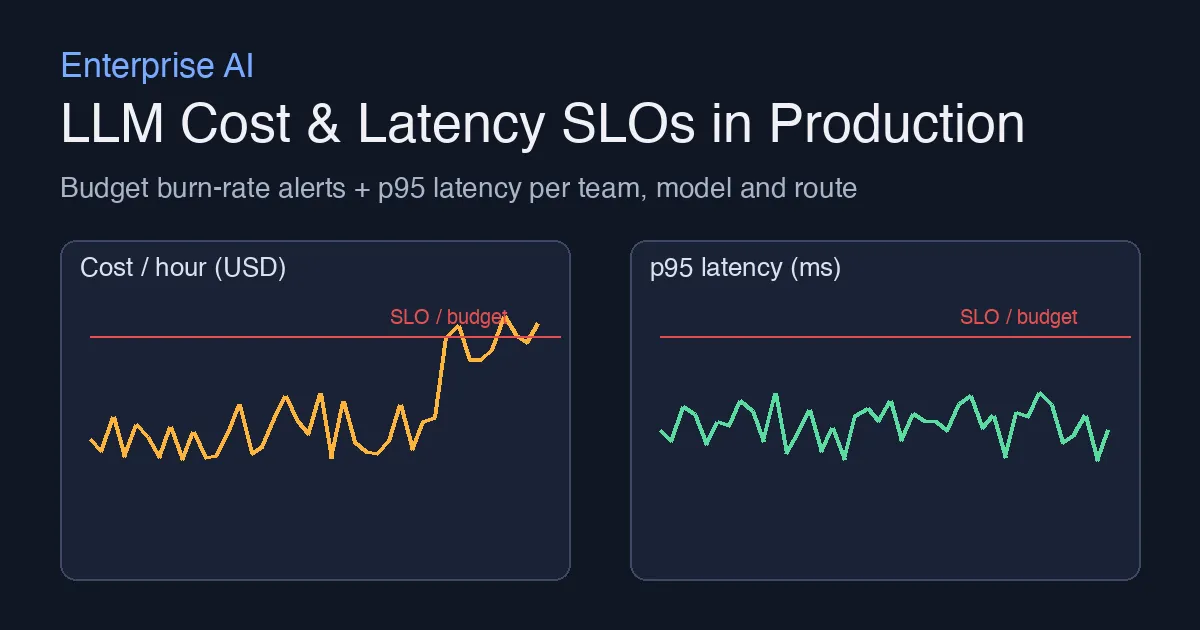
Define cost and p95 latency SLOs per team and model for Azure OpenAI, compute burn rates in KQL, and page only when both windows are on fire.
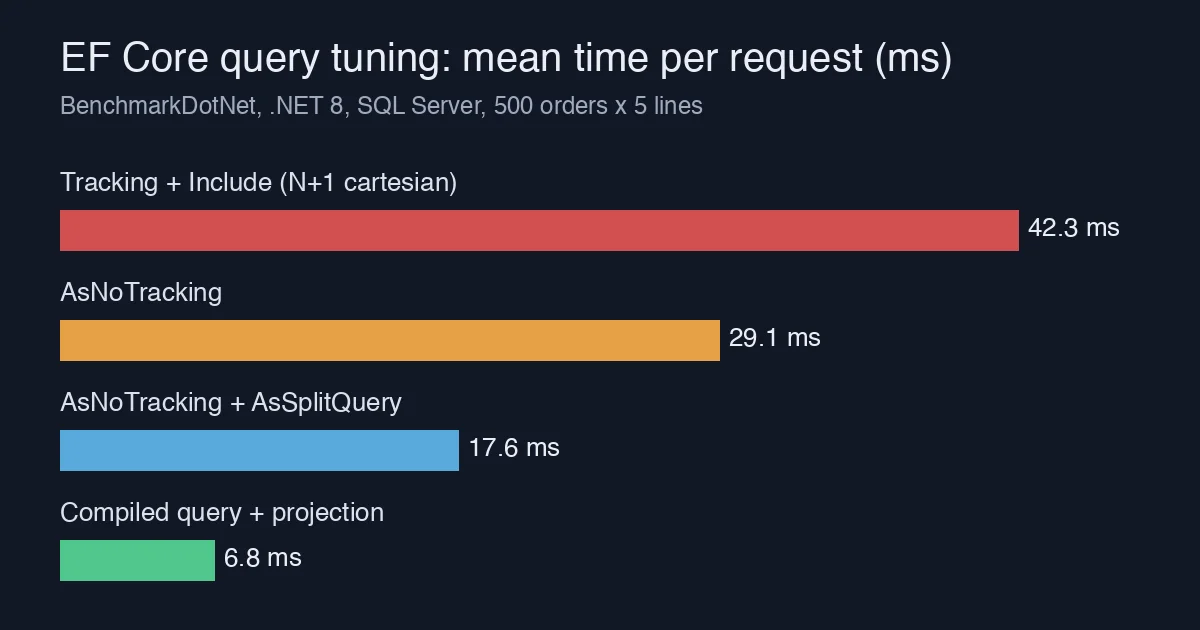
Tune EF Core read paths with AsNoTracking, AsSplitQuery, projections and compiled queries. Benchmark table shows a 42 ms query dropping to under 7 ms.
Five OData query mistakes that slow down .NET clients talking to D365 or ASP.NET Core OData APIs, with before/after queries and a request-flow diagram.